Category: Development

  • Data Conditioning for Snowflake ID Compression

    close up photography of snowflake
    Photo by Egor Kamelev on Pexels.com

    I was reminded recently of a question that had been in the back of my mind when I was working at Twitter. With the exception of very old content, IDs of tweets and other entities like users are so-called “snowflake IDs” – unique timestamped integer IDs, constructed specifically to try and avoid ID collisions in a high volume application. Snowflake IDs use a certain number of bits for the timestamp, some bits to identify the ID generator from which the value came, and a set of bits for a “sequence number”, to disambiguate IDs that are generated within the same timestamp.

    If you have a set of IDs generated using this scheme, you might notice that, in practice, many of the bits have the same value across IDs. For example, there is a limited number of ID generator hosts in use – you might only see a handful of different values, in practice. Most of the ID generator bits in your IDs are going to match, or perhaps only a couple of them might vary at all. The sequence numbers demonstrate the same sort of concentration – most of the time, the sequence number will be 0, since it is rare to generate many IDs within the timestamp resolution, and that 0 across lots of IDs would compress very well. And even the timestamps themselves will have many common values across a block of IDs, given the limited time windows in which services that use these formats have been operating. There just seems to be a lot of commonality across ID values, inherent to the format itself.

    The question that I had asked myself was, how much could you compress these ID values, if you performed a bitwise transpose on the ID values (like BitShuffle), before compressing them? And how would this compare to just naively compressing these blocks of IDs with something like Brotli? It seemed to me that, after transposing the ID values, you might end up with very long runs of bits that all have the same value, which would be a great target for compression algorithms.

    I spent a little time writing an experimental harness in F# to allow me to test this idea, and collect data about the effectiveness of applying different filters or conditioning techniques on the data, before compressing it. As configured out of the box, it runs 5000 trials, generating 3200 IDs per trial and running them through each of a set of data processing pipelines. I’ve put the code up on GitHub, along with a spreadsheet with graphs illustrating the effectiveness of each method from a run I did locally.
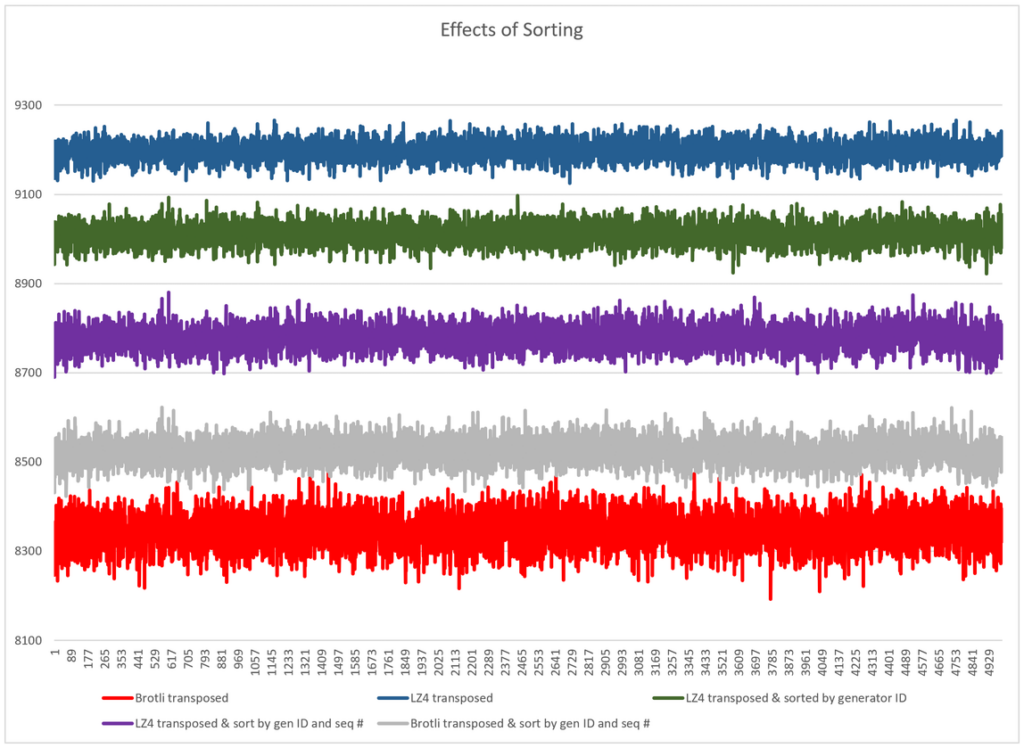
    A quick summary of the results:

    • General-purpose compression algorithms like Brotli perform well when compressing this data, even without any other conditioning applied to it.
    • Performance-oriented algorithms like LZ4 produce significantly larger (60-100%) results than, say, Brotli, when no data conditioning is performed. Compared with uncompressed data, LZ4 compression without any further data conditioning only results in a ~35% space savings.
    • The bitwise transposition technique works well for the algorithms like Brotli, reducing the size of the final data by another 15% or so. But it makes a huge difference for LZ4 and the like, cutting the size of the final data by another 45% or so, and putting it within 10% of the size of Brotli-compressed data.
    • Grouping IDs by their generator ID and sequence numbers before applying the transpose results in another ~5% improvement in the final size of the LZ4-compressed data. As you can see in the graph above, this grouping change actually made Brotli compression significantly worse than with transposition alone, which is interesting.
    • There didn’t seem to be any significant difference in changing the sort direction of the IDs in the block.
    • Compared to the uncompressed data, “Brotli with transpose” reduced the size of the ID data by ~66%. “LZ4 with grouping and transpose” reduced the size of the ID data by ~65.7%.

    These results suggest quite strongly that proper data conditioning before applying compression to snowflake IDs can result in pretty big space savings, on the order of ~66%. And if you’re using an algorithm like LZ4, you’ll definitely want to transpose your ID values before compression. If you have large sets of IDs like this in your system, either at rest, or as part of calls or messages in your system, it might be worth trying these techniques to reduce data size.

    If you’re interested in playing around with the parameters of this test, you can easily tweak them in the source, and re-run it again locally. You can also try configuring your own data conditioning and compression pipeline, and compare it against the ones that are already there.

  • Ludum Linguarum: Aurora

    (Ludum Linguarum is an open source project that I recently started, and whose creation I’ve been documenting in a series of posts. Its purpose is to let you pull localized content from games, and make flash cards for learning another language. It can be found on GitHub.)

    In this post, I’ll talk a little bit about Ludum Linguarum’s support for some of the Aurora-engine based games that are out there. The Aurora engine was Bioware’s evolution of its earlier Infinity Engine, and was used in quite a few games overall.

    Motivation

    There are quite a few games with large amounts of text that were produced with the Aurora engine (including one that I worked on), so it seems quite natural to try and target it for extraction. The text in these games can also be categorized in some ways that I think are interesting, in the context of language learning – there are really short snippets or words (item names, spell names, skill names, etc.), as well as really lengthy bits of dialogue that might be good translation exercises. Additionally, there’s quite a bit of official and unofficial documentation out there around its file formats.

    Goals for Extraction

    The raw strings for the game are (mostly) located inside the talk table files. However, just extracting the talk tables would lose all context around how the strings are actually used in the game. For example, the spell names, feat names, creature names, dialogues, and so on, are all jumbled together in the talk table. It sounds like a small thing, but I feel that creating a taxonomy (in the form of “lessons”) would make a big difference in the usefulness of the end product. Unfortunately, it also makes a huge difference in the amount of effort needed to extract all of this data!

    How it all went

    I spent quite a bit of time writing file-format-specific code, for things like the TLK table format, the BIF and KEY packed resource formats, the ERF archive format, and the generic GFF format. On top of that, then there was code to deal with the dialogue format that gets serialized into a GFF.

    I started with the original Neverwinter Nights, and then moved on to Jade Empire. The console-based Aurora engine games used some variant file formats (binary 2DAs, RIM files, etc.) that needed a little extra work to deal with, but there was enough information about these available on the Internet that I was able to support them without too much hassle.

    Once I had the basic file parsing code in place, it was just a matter of constructing the “recipe” of how to extract the game strings. This mostly involved sifting through all of the 2DA files for each game, looking for columns that represented “string refs” (i.e. keys into the talk table database) – extracting dialogues was much simpler since they were already in their own files, and their contents were unambiguous.

    Comparison between C# and F# implementations

    I had basically written all of this file parsing code before (in the C# 2.0 era, so without LINQ), but this time around I was writing it with F#. I found it very interesting to compare the process of writing the new implementation, with what I remember from working on Neverwinter Nights 2 more than 10 years ago.

    The F# code is a lot more concise – I would estimate on the order of 5-7x. It isn’t quite an apples-to-apples comparison with what I did earlier (for example, serialization is not supported, only deserializataion), but it’s still much, much smaller. I suspect that adding serialization support wouldn’t be a huge amount of additional code, for what it’s worth.

    Record types and list comprehensions really help condense a lot of the boilerplate code involved in supporting a new file format, and match expressions are both more compact, and safer when dealing with enumerated types and other sets of conditional expressions. I also got lots of good usage out of Option types, particularly within the 2DA handling, where it very neatly encapsulated default cell functionality.

    But I think the thing that accounts for the biggest difference between my old C# implementation and the new F# implementation, is the range of functional abstract data types available – or, to put it another way, the lack of LINQ in my C# implementation. If LINQ were available at the time I was working on Neverwinter Nights 2, I think my code would have looked a lot more like the F# version, with liberal use of Select()/map() and Where()/filter(). These operations replace very verbose blocks of object construction and selective copying, often in a single line, which is an enormous savings in code size and improvement in clarity.

    I feel like there is still a lot of bespoke logic involved, for extracting the individual bits and pieces of each format, but that doesn’t seem to be avoidable – the formats are not self-describing, and it seemed like it would be overkill to try and construct a meta-definition of the GFF-based formats.

    Summary

    Overall, I was pretty pleased with how this went. While it was a decent amount of work to support each file format, once that code was all written, the process of creating the game-specific recipe to extract strings was pretty straightforward. There weren’t really any surprises in the implementation process, which was definitely not the case for the game that I’ll talk about in my next set of posts.

  • Ludum Linguarum: The Simple Stuff

    (Ludum Linguarum is an open source project that I recently started, and whose creation I’ve been documenting in a series of posts. Its purpose is to let you pull localized content from games, and make flash cards for learning another language. It can be found on GitHub.)

    When I started this project, I figured that support for individual games would fall into one of a small set of categories:

    • Low effort, where the strings are either in a simple text file or some sort of well-structured file format like XML, where many good tools already exist to pull it apart.
    • Cases where the file formats, while bespoke, are well documented, and where there may be tools and code that already exist to parse the file formats.
    • The really hard cases – ones where there isn’t a lot of (or any) extant information about how the game stores its resources, and extracting strings and metadata about them is more of a reverse-engineering exercise than anything else.

    In this post, I’ll talk very quickly about a few really simple examples of games that I was able to knock out very quickly: King of Fighters ‘98, King of Fighters 2002, Magical Drop V, and Skulls of the Shogun.

    King of Fighters ‘98 and King of Fighters 2002

    While I was working on this project, I started on some of the other supported games first. But then, I decided to take a little break, and see if there were any games out there that would be really trivial to support. I just started browsing through my Steam library, and realized that fighting games were probably a good candidate – they contain limited amounts of text, but were definitely globalized.

    Both of these games use the Xbox 360 XDK’s XUI library formats to present their UI. (I determined this by the presence of some files and directories with “xui” in their name.) All of the strings in the game are inside a file conveniently named strings.txt inside the data directory.

    This is a tab-delimited format with just four columns – a key for the string, a “category” comment field, and then columns for each supported language – “en” for English, and “jp” for Japan. (It’s interesting that the country code rather than the language code was used for Japan – I’m not sure if that was an unintentional mistake.)

    In this case, it’s super simple to extract all of the strings, because of the simple formatting, and the one place that I need to look to find them all. I simply read in the file, and directly map the key column to the per-language text for each card.

    (It’s worth noting that King of Fighters XIII doesn’t use the same format or engine, so I wasn’t able to just add support for it using the same code.)

    Magical Drop V

    Adding support for Magical Drop V just involved reading some XML files within its localization subdirectory, and massaging them slightly to remove invalid and undesirable text. For example, ampersands were not escaped in the XML files, which caused the .NET framework’s XML parser to complain. I also stripped out some obvious placeholder values (“<string placeholder>”).

    Overall, it was really quite simple to add support for this game, with the game-specific code only running to about 50 lines.

    Skulls of the Shogun

    Skulls of the Shogun is a game built on XNA and MonoGame, and actually uses the .NET framework’s globalization support to localize its strings. Thus, I was able to use the framework’s support for loading satellite assemblies to pull out both the string keys used to refer to the strings, as well as the content itself, quite easily.

    I actually spent more time determining that I had to load the assemblies using the reflection-only context, in order to keep my library and console application bit-length-independent, than writing the rest of the code to support this game!

  • Ludum Linguarum: The Tools

    (Ludum Linguarum is an open source project that I recently started, and whose creation I’ve been documenting in a series of posts. Its purpose is to let you pull localized content from games, and make flash cards for learning another language. It can be found on GitHub.)

    When I started working on Ludum Linguarum, I decided to use it as an opportunity to exercise what I had been learning about the F# language on the side. This might seem like kind of a strange decision out of context, but there were a few reasons why I felt that this made sense:

    • I already had a good bit of familiarity with the .NET stack, having spent a good chunk of my years in the gaming industry writing tools in C#.
    • Because of the frequent use of C# in games and editors, I felt that there would be a greater likelihood of me finding useful, easy-to-integrate libraries and documentation for reverse engineering games than on other stacks.
    • I write Scala at my day job, so I figured that I would be reasonably well-equipped to deal with the functional programming aspects of the language, even if I had never really touched Ocaml before.

    At the very beginning of the project, I was working on learning F# on my commute, using Mono and MonoDevelop on an old netbook that I threw Ubuntu on. This worked (in that it is totally possible and viable to write F# and .NET code on non-Windows platforms), but later on I got a proper new laptop, threw Visual Studio 2015 on it, and never looked back. The added benefit of doing this, of course, was that, running under Windows, I could easily install and run the games that I was reverse engineering.

    The benefits

    All in all, I have been very pleased with my decision to use F#. Using a functional-first language let me construct composable, easily-testable pipelines, and I feel this really saved me a bunch of time as the project grew. The language is very similar in capabilities to Scala for application code, albeit with significantly different syntax and a slight verbosity tax.

    When I think back to similar code I’ve written in the past, I feel that my F# code is more concise, easier to understand, and with less room for bugs to creep in, compared to C++ and C#. This applies both for simple parts of the code, as well as much more complex parts. In a future post, I’ll go into this in some more detail.

    I would go so far as to say that the things that slowed me down the most were when I strayed furthest from the functional style, and just used the full console application and the full game data as my testbed. (The reason I did this is that it can be a bit of a pain to construct test data that is compact, concise, and doesn’t include any actual copyrighted material.) As long as I wasn’t too eager, moved at a reasonable pace, and built up a decent test corpus, things worked out well.

    Project setup

    Initially, I used the standard .fsproj and solution setup in VS. The project was set up as a plugin-based system, where all main build outputs were copied into a single output directory, and NUnit test projects were simply run in-place. This worked OK, but as I got closer to actually releasing the first version of the project, I decided that it would be better to migrate the project to the FAKE build system and Paket dependency manager. (Using those makes it simpler to keep dependencies up-to-date, and hopefully easier for the curious or motivated to build and run the project.)

    I used the open source F# Project Scaffold, and reconstructed my old project setup. It took a little bit of experimentation, but I was able to get up and running pretty quickly. I did run into an issue where the recently-released NUnit 3 isn’t supported by FAKE, and I did have to do some legwork to get everything building with F# 4 and .NET framework 4.6.1, but it wasn’t too bad. Now I have a very simple system to build, test, and package the project for release.

    The latter is particularly important – I don’t have a lot of extra time to spend on overhead like manually making builds and uploading them, so it’s much easier for me to change the way I work, and change my project to conform to some existing conventions. One example of this is that the console program used to have no project dependencies on its plugins – they were copied as a post-build step into a separate plugins directory in the build output. This was done out of a bit of a purist mindset (and was what I had done on some other projects in the past) – but when I migrated to FAKE, this presented some problems, as it was difficult to duplicate this exact behavior. The solution was to simply abandon purity, adjust the way that I did things, and just add project dependencies to the console application against the plugins. Realistically speaking, anyone developing a plugin is probably going to have the full source handy anyway, so why get hung up on this?

    Other libraries

    So far, I’ve pulled in just a few other libraries. One is sqlite-net, a SQLite wrapper, and another is CommandLineParser, to allow me to construct verb-driven command line handling in the console application. I spent a little while wrestling with both, but now I have a couple of wrappers and things generally set up in a way that works well. (I actually switched back and forth between the old version of CommandLineParser and the new beta one, and wound up sticking with the new beta as it fixed at least one annoying crash relating to help text rendering when using verbs.) I also wound up adding the venerable SharpZipLib library for zip archive support.

    Summary

    In summary, I’m glad that I have a setup now, using FAKE and Paket via the F# project scaffold, which is good for rapid development in Visual Studio, has good testing support, and one-line release packaging and deployment. There were a few bumps along the way in arriving at this setup, but I can wholeheartedly recommend it to anyone working in this ecosystem.

  • Introducing Ludum Linguarum

    I’ve been working on a side project for some time now, and it’s gotten far enough along that it’s worth releasing it, and discussing it. It’s called Ludum Linguarum (LL) – a little awkward, yeah, but I figured that a unique name would be better in this case than spending a lot of time trying to find an available-yet-expressive one.

    What does it do?

    Well, it’s intended to be a tool for extracting localized resources from games, and then converting them into language learning resources. In other words, the end goal is that you can turn your Steam library (full of games that you bought for $0.99 in some random bundle) into material to help you learn another language.

    The current version pulls strings from games, and turns them into flash cards for use with Anki (and compatible apps). LL supports 21 games right now, and the goal is to expand that over time.

    Why write something like this?

    Well, it involves two things that have always interested me (games and languages), and as far as I know, nothing else like this exists! (subs2srs is a tool in a similar vein, but it generates flash cards from subtitled videos instead.) I figure you might be able to get a little extra motivation and drive by learning another language in the context of gaming.

    Another reason is that the vocabulary of games is often well off the beaten path of most language courses – I don’t think that Rosetta Stone or even Duolingo is going to tell you that “magic missile” is Zauberfaust in German. There aren’t that many opportunities to learn this stuff otherwise – think of it like professional vocabulary, but for a really weird job.

    I also find cultural differences interesting, and that includes the way that game content gets translated. Seeing how colloquialisms and “realistic” conversation get translated is really interesting to me – I get a huge kick out of learning that platt wie Flundern is how someone chose to translate “flat as a pancake.”

    Finally, game content in itself is an interesting treasure trove where you can often see the remnants of things that were tried and abandoned, or cut in order to get the product to the finish line. And naturally, some of the most common types of remnants are text and audio.

    Next Posts

    I’m going to spend the next few posts talking about the development of Ludum Linguarum, and writing the code to extract strings out of the first few games it supports. There were quite a few interesting problems that came up while getting to this point, and a few interesting tidbits and trivia that I can share about some of the supported games.

  • Analysis of Yakuza 5 Hack Videos

    I happen to be pretty hyped over the upcoming US release of Yakuza 5 — I’m a big fan of the series’ odd mix of ridiculous melodrama, wide variety of activities and minigames, and really satisfying combat. So naturally, after the localization was announced, I went around looking for videos of the game to watch. First off, I found this amazingly comprehensive and lovingly-assembled survey of the whole series — it’s not really related to the rest of this post, but if you’ve never seen these games it’s worth watching to get a glimpse of how unique they are, and what’s so appealing about them to me.

    Then, I found some videos of some hacks that someone apparently made to the game, to allow the player to play as Haruka and another female character (Mai — no idea what her place in the story is). During the normal story arc, there is a chapter where you play as Haruka — however, her fights are rhythm games and dance battles, not the sort of bare-knuckle brawls for which the series is famous. This hack instead allows you to play as these characters during other chapters of the game, where you engage in tons and tons of fistfights. And, somewhat surprisingly, if you watch the videos, it looks pretty good!

    So, putting on my ex-game developer hat, what do these videos tell us about the way the game is built, and why this was possible? And is adding a new playable character to the game as simple as these videos make it seem? Here are some of my observations and speculation on how this works, and its limitations.

    • The female and male characters must be animated using the same skeleton. Basically, because all of the combat animations that these characters are using are the same ones that the standard playable characters use, Haruka and Mai must be built and animated on the same basic skeletons as Kiryu, Saejima, Akiyama, and Shinada. This is a little surprising to me, but it goes a long way to explaining why the female characters in this series always seem to…uh, have a somewhat mannish feel to them. I’m guessing that, for the original PS2 games, that this was done to save memory, and then brought forward because it worked well enough and making unique skeletons would require duplicating an already-large animation set.
    • Haruka and Mai are missing a lot of animation metadata. The most obvious case is when Haruka goes to light up a relaxing cigarette after beating the tar out of countless schlubs, just like uncle Kiryu.
    • The smoke from the cigarette comes out of Haruka’s chest — or, more accurately, the origin (0, 0, 0) of the character. There’s a missing animation attachment point in Haruka’s metadata, and the game engine falls back to the origin. Interestingly, Mai seems to have this attachment point — the smoke appears in the correct place for her.

      Another example of missing metadata is this HEAT attack with a bowling ball — it pops away from Haruka’s hand and looks like it’s stuck on her nose. And if you freeze-frame a similar HEAT attack with a beer bottle, you can see that the bottle looks like it’s stuck on her lips.

      I believe there are also missing camera focus points — for example, at the end of this HEAT move, the camera seems to be focused on the origin point of Haruka, and her face is off camera. If I remember correctly, this move looks different when performed by one of the other player characters — the camera tracks the head and it’s in the frame.

    • They’re also missing a lot of animations. The easiest case to spot is that Haruka and Mai’s faces remain completely expressionless, and possibly unblinking, during fights — they don’t have any combat “barks” (voice + facial animation), and they don’t play any reaction or pain facial animations as they lay waste to their foes. While it kind of lends a comic tone to the video, this would definitely not be acceptable for an officially supported character. It just looks strange.
    • The game’s IK seems to work OK with these characters. I had kind of assumed that the engine supported IK, given that a lot of the close combat grabs in the game look pretty good. When Haruka grabs a thug by the hand, that’s a pretty strong signal to me that they’re doing some limited IK, because if they weren’t, you would probably see a gap in the throw animation as Haruka’s character is physically smaller than, say, Kiryu’s. Another example of this is Mai kicking the sign stuck on a thug’s head — it’s just too unlikely that it would look good without IK support.

      Note that there are still some cases where it looks like they don’t normally use IK, and just rely on the animations fitting the sizes of the characters — Haruka lifting up a thug looks pretty bad, as her hand is nowhere near the thug’s chest.

    • Haruka and Mai’s hair is not built to be animated during combat. In the case of Mai, her hair basically doesn’t move at all. And Haruka’s hair physics object was clearly conditioned to look good during movement animations, but not tuned at all for anything that would look like combat, with its frequent flips, tumbles, falls, and dashes. It’s all over the place constantly.
    • Both characters seem to be using Akiyama’s move set. But I can’t tell if this is just a convenience, a deliberate stylistic choice on the part of the author, or that none of the others would work. I think it would be kind of funny to see them using Saejima’s brawling moves, though.
    • Surprisingly, there was no content protection on the game assets. Presumably the author of these videos was able to simply pull out the PS3 HDD, and modify the files directly on the hard drive to point a character definition to Haruka or Mai’s models. It’s a little surprising to me that these were left unprotected, but perhaps Japan has less societal anxiety about hot coffee than the US. Maybe I should have a look at the installed data, to see if I can verify any of my conjecture here.

    In closing, I think these are really neat, fun videos to watch, and that it would be very cool if female characters in future Yakuza installments were able to fight and brawl. But there are enough rough edges and missing content in this hack, that it should be clear that making them fully playable is not just a matter of flipping a switch (or deciding to change the story) and suddenly having Haruka powerbombing fools alongside her uncle Kiryu. There’s a lot of missing content and additional polish that would need to go into making Haruka and Mai fully first-class fighting characters in the game.

    Questions or comments on my analysis are welcome!

  • Tinfoil hat time

    I just thought I would share an amusing anecdote from my time at Netflix, related to wi-fi networking in our office. Because many devices that support Netflix have built-in wi-fi, we would test streaming with wi-fi connections to ensure that the experience was still satisfactory. Pretty standard stuff.

    At one point, though, we ran into a mysterious problem with wi-fi networking on one of our supported device types. Thinking that perhaps there was an issue with the wi-fi adapter on the device, or the signal from the router, someone did a WLAN survey to see how many wi-fi networks were visible from our corner of the office.

    It turns out that there were no fewer than 150 access points visible from there. Yes, 150 access points. That’s what happens when you have a huge number of people, working on a huge array of different devices, with different network configurations, and in different working environments.

    Of course, this discovery led to more than a few jokes about sterilization, CIA mind control, and space madness.

    (It turns out that the root cause of the problem didn’t have anything to do with wi-fi interference — it was actually a firmware bug on the device, which was triggered by a separate firmware update to the wireless access points in our building. Pretty crazy!)

  • Memory Card Bugs (and a note about static analysis)

    I was watching John Carmack’s QuakeCon 2011 keynote, and he mentioned that Rage was currently in the stage where they are creating cert builds, and just fixing bugs like (paraphrased) “getting a multiplayer invite and pulling your memory card out.” Memory card bugs are one of those things that tend to be a big annoyance for game programmers, because of the number of asynchronous use cases that need to be handled and the need to tie what are essentially supposed to be serial operations to a game that may be doing many other things in parallel. (Memory card support was optional on the original Xbox, due to the guaranteed presence of the internal hard drive. Accordingly, hardly any games actually support managing memory cards directly in-game.)

    Carmack’s mention of memory card bugs reminded me of a funny story from Obsidian. For the Onyx Engine, one of my coworkers was working on writing the save/load code and then fixing bugs in the system, including memory card bugs on Xbox 360. Many of these bugs were timing-specific, so he would remove and reinsert his test memory card to try and reproduce the bug. Eventually, though, the first memory card slot on his development kit broke from the repeated (and potentially forceful, because of the need to try and reproduce specific timings) insertions and removals of the memory card. He had to switch over to the second slot on the kit — which, thankfully, survived until the project was over.

    Another thing that came up in Carmack’s keynote is the use of static code analysis. He mentioned that id have drunk the proverbial Kool-Aid as far as static code analysis goes, and mentioned that turning on the “/analyze” switch for Xbox 360 builds (a flag that the XDK compiler supports — normally I think you need the Ultimate version of Visual Studio) brought to light many issues with their codebase. I can also vouch for this — I used to do this semi-regularly at Obsidian, and every time I ran it there were several subtle bugs that were sniffed out. It’s really worth using if you have it available.

  • Fallout: New Vegas has gone gold

    Here’s the official announcement on the Bethesda blog, along with pictures of an awesome Fallout: New Vegas themed cake that one of the designers at Obsidian got for his birthday.

    I pitched in for a couple of months prior to certification to help get it ready for ship. I hope everyone enjoys playing it once it’s out!

  • A Gross Overgeneralization

    From David Chisnall:

    If you find yourself optimizing your code, then it means that the author of your compiler has failed.

    This is just very, very untrue. Even if you strike algorithmic optimization from the picture, code optimization is still a very important and useful skill to have no matter what sort of programming you’re doing. Knowing your target platform, knowing the behavior of your compiler or interpreter, and knowing your data (hat tip again to Mike Acton for driving this point home to me) can provide you with ideas on how to transform your code and realize massive performance gains.

    If you’re writing performance-critical code, no compiler is going to do everything for you – the best optimizer is still between your ears. The idea that poorly-performing code can be blamed on the compiler is simply naïve and defeatist.